DSU on Tree
Introduction
What is a heuristic?
A heuristic is an optimization of an algorithm that rests on human experience and intuition.
The most familiar example is the small-to-large merging heuristic of a disjoint set union. The code looks like this:
1 2 3 4 5 6 | |
Here, given two sets of different sizes, we merge the smaller set into the larger one, not the larger into the smaller.
Why? The size of a set can be thought of as its height (under normal circumstances), and attaching the set of smaller height to the one of greater height clearly helps us find the parent.
This optimization, making the tree of smaller height a subtree of the taller one, is called small-to-large merging.
The algorithm
DSU on tree is an algorithm for certain offline problems on trees. It is at least as fast as most alternatives, and easier to understand and to implement.
Consider the following problem: Counting Distinct Colors on a Tree.
Motivating example
Given a tree with \(n\) nodes rooted at \(1\), in which node \(u\) has color \(c_u\), find for every node \(u\) how many distinct colors occur in the subtree rooted at \(u\).
\(n\le 2\times 10^5\).
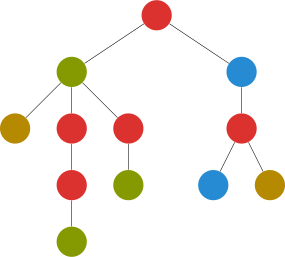
Problems like this are mostly solved with a heavy load of data structures (nested trees and the like). If the queries can be answered offline, is there a simpler way?
Procedure
Since we may work offline, let us precompute all the answers and then output each one in \(O(1)\).
Brute-force preprocessing takes \(O(n^2)\) time: it runs one traversal for every child node, each traversal is clearly of the same order of magnitude as \(n\), and there are \(n\) nodes, hence \(O(n^2)\).
The answer of a node is determined by its subtrees and the node itself. We will use this property to solve the problem.
First precompute the subtree size and the heavy child of every node. As in heavy-light decomposition, the heavy child is the child whose subtree has the most nodes. This clearly takes \(O(n)\).
Let \(cnt_i\) be the number of occurrences of color \(i\), and \(ans_u\) the answer for node \(u\).
To process a node \(u\), go through the following steps:
- First traverse the light (non-heavy) children of \(u\) and compute their answers, but do not keep their effect on the \(cnt\) array afterwards;
- traverse its heavy child and keep its effect on the \(cnt\) array;
- traverse the nodes in the subtrees of the light children of \(u\) once more and add their contributions, which gives the answer for \(u\).
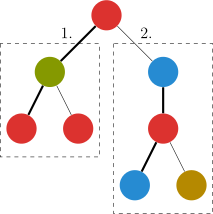
The figure above shows an example.
So for each node we traverse its heavy subtree once and its non-heavy subtrees twice, which is clearly the cheapest way.
Carrying out this procedure yields the answers for all subtrees of the node.
Why not merge steps 1 and 3? Because one \(cnt\) array cannot serve several subtrees at once, and more arrays would take too much space: everything has to fit in \(O(n)\) space.
Clearly, if a node \(u\) is traversed \(x\) times, then its heavy child is traversed \(x\) times and its light children (if it has any) \(2x\) times.
Note that \(cnt\) must be reset to zero after every traversal, except that of the heavy child.
Proof
Define heavy edges and light edges as in heavy-light decomposition (an edge to a heavy child is heavy, all the others are light). The figure below illustrates heavy children and heavy edges. For a tree with \(n\) nodes:
The path from the root to any node of the tree contains at most \(\log n\) light edges. Suppose there are \(x\) light edges between the root and the node, and let the subtree of the node have size \(y\). The child at the lower end of a light edge has a subtree less than half the size of its parent's (if it were more than half, the edge would not be light), so \(y<n/2^x\). Clearly \(n>2^x\), and therefore \(x<\log n\).
Moreover, if a node is the heavy child of its parent, its subtree is the largest among its siblings, so on the path from any node to the root, the parent at the upper end of a heavy edge never traverses this node while computing its answer. Hence the number of times a node is traversed equals the number of light edges on its path to the root, \(+1\) (the \(+1\) is there because the node itself has to be traversed). So this number is \(\le\log n+1\), the total time complexity is \(O(n(\log n+1))=O(n\log n)\), and outputting the answers costs \(O(m)\).
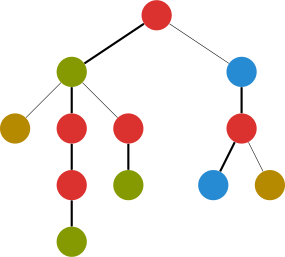
The thick edges in the figure are heavy edges; the child at the lower end of a heavy edge is a heavy child
Optimization
As the proof pointed out, DSU on tree borrows the notions of heavy and light children from heavy-light decomposition to speed up merging. That being so, we can also use the DFS order produced by heavy-light decomposition directly, turn the recursion into iteration, and reduce the constant factor of DSU on tree further.
Any DFS order has the following property: the subtree of a node is contiguous in it. So we can scan the DFS order array backwards. This guarantees that when we reach a node, all the other nodes of its subtree have already been processed.
The DFS order produced by heavy-light decomposition has a further nice property: every heavy path is contiguous in it. So when we scan the nodes in reverse DFS order, the node visited right after the top of a heavy path is never the parent of that top node, so the effect of the top node has to be cleared. For a node that is not the top of a heavy path, on the other hand, the node visited just before it is either its own heavy child or a node of another branch whose effect has already been cleared, so the effect can simply be inherited. On top of that, use the DFS order to add the effect of all light children quickly, and record the answer.
This procedure is the non-recursive, or iterative, implementation of DSU on tree (also called its DFS-order implementation). Compared with the original recursive implementation, it saves the time and space overhead of recursive function calls, which is a considerable constant-factor optimization; on trees that contain many chain-like structures in particular, it has a marked advantage in stack space.
Implementation
Reference implementation
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 | |
Applications
-
Problems for which the problem setter's intended solution is DSU on tree
One example is CF741D. Given a tree in which the weight of every node is a letter from 'a' to 'v', each query asks for a path inside a subtree such that the characters on the path can be rearranged into a palindrome.
Since the palindrome is formed from a permutation of the characters, a character that occurs twice might as well not occur at all. In other words, the path has to satisfy that at most one character occurs an odd number of times.
The straightforward approach runs a DFS from every node and, at each node it reaches, enumerates all letters by brute force to find the paths whose XOR with it has at most one bit equal to 1, then takes the longest. This is \(O(n^2\log n)\); DSU on tree brings it down to \(O(n\log^2n)\). For the details, see the further reading below.
-
Problems where DSU on tree works as an ad hoc heuristic
It can pick up partial scores on some nested-trees problems (those without updates), and its complexity beats the \(O(n\sqrt{m})\) of Mo's algorithm on trees.
Practice problems
Problem summary: the nodes of a tree have colors, and a color dominates a subtree if and only if no other color occurs in that subtree more often than it does. For each subtree, find the sum of all colors that dominate it.
References and further reading
DSU on tree as introduced by the author of CF741D
This page is an unofficial English translation of the original OI Wiki page (revision 9bb3a8e6), machine-translated by Claude Fable 5.2 on 2026-11-16. It has been modified from the original by translation and may contain errors. It is not endorsed by OI Wiki.
Found a translation problem? Report it on GitHub.
Authors of the original page: abc1763613206, cesonic, Ir1d, MingqiHuang, xinchengo, xiaofu-15191, hsefz-ChenJunJie, 24OI-bot, zirnc, StudyingFather, Penguint, Alpacabla, woshiluo, Enter-tainer, sshwy, mcendu, ksyx, CroMarmot, iamtwz, SmallTualatin, Tiphereth-A, r-value, alphagocc, Early0v0, Enonya, StableAgOH, c-forrest (full contribution history)
All content on this page is provided under the terms of CC BY-SA 4.0 and SATA; additional terms may apply.