Aliens Trick (WQS Binary Search)
Introduction
This article describes the Aliens trick, a way of optimizing dynamic programming problems. In China it is known as WQS binary search, and other texts call it weighted binary search, convex-optimization DP, convex totally monotone DP or the Lagrange multiplier method. It was first written up by Qinshi Wang in On a Class of Binary-Search Methods.
The Aliens trick is typically used for optimization problems of the following kind: a constraint on a count makes them expensive to solve directly, but once that constraint is removed the problem becomes much easier.
Suppose, for example, that we must choose \(m\) of \(n\) items so as to optimize some fairly complicated objective function. Let \(f(i,j)\) be the optimal value of the objective when \(j\) of the first \(i\) items are chosen; the answer to the original problem is then \(f(n,m)\). In problems like this the recurrence is usually two-dimensional, and implementing it directly takes \(O(nm)\) time, which is too slow.
Suppose further that the optimization problem without the count constraint is easy. The number of items its optimal solution chooses need not satisfy the count constraint of the original problem, however. Say it chooses too many. Then we can attach a fixed penalty \(k\) to every chosen item (this is the "weight" in "weighted binary search") and again solve the problem without the count constraint. The optimal number of chosen items depends on \(k\), and it changes monotonically as \(k\) changes. So a binary search finds a \(k\) for which the optimal number is exactly \(m\). Let \(f_k(n)\) be the optimal value of the objective for this \(k\). Removing the loss in value caused by the penalties gives the answer to the original problem, \(f(n,m)=f_k(n)-km\). If solving the penalized problem once takes \(O(T(n))\) time, the whole algorithm takes only \(O(T(n)\log L)\), where \(O(\log L)\) is the number of times the binary search on \(k\) has to solve it.
This is the basic idea of the Aliens trick. It works only if \(f(n,m)\) is convex in \(m\), though: otherwise there may be no penalty \(k\) for which the optimal number is exactly \(m\). This is also why this DP optimization is often called "convex-optimization DP" or "convex totally monotone DP".
Traditional method
Let the nonempty set \(X\) be the (finite) decision space, let \(f:X\rightarrow\mathbf R\) be the objective function, and let a further function \(g:X\rightarrow\mathbf R^d\) impose the constraints. The problem to solve can be seen as evaluating, at some point, the value function \(v(y)\) of the following optimization problem:
In the count-constrained problem above, for example, \(X\) is the family of all subsets of the set of items, \(x\in X\) is a single subset, \(f(x)\) is the value of that subset, and \(g(x)\) is the number of elements of the subset \(x\). Of course \(g(x)\) need not be a count; later sections give examples of much more general constraints.
Conventions
For convenience, this article discusses only problems that minimize the objective function. Maximization problems are analogous: replace the convex (convex downward) functions of this article by concave (convex upward) functions. Alternatively, add a minus sign to turn the maximization of an objective function into the minimization of its negative.
Geometric intuition
Most problems in competitive programming are combinatorial optimization problems, and the decision space \(X\) usually has no good structure. So we study instead the set
The traditional method mainly handles the case \(d=1\), that is, a single constraint. The figure below shows what the point set \(\mathcal D\) may look like in this case.
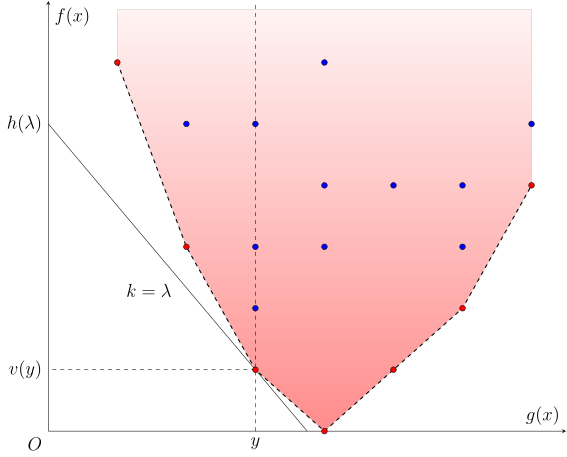
The red and blue points in the figure form the set \(\mathcal D\), obtained by projecting every possible choice in \(X\) onto the plane \((g(x),f(x))\). The original problem asks for \(v(y)\), the smallest ordinate among the points with abscissa \(y\). As \(y\) varies, the points \((y,v(y))\) make up the set of red points in the figure.
To find the ordinate of the point \((y,v(y))\), cut the set \(\mathcal D\) with lines of slope \(\lambda\in\mathbf R\). As the figure shows, when the slope is chosen well, the line through \((y,v(y))\) has the smallest intercept \(f(x)-\lambda g(x)\) among all lines of slope \(\lambda\) through a point of \(\mathcal D\). Denote this minimum by
Since \((y,v(y))\) lies on that line as well, this gives the solution of the original problem:
Assume that \(h(\lambda)\) is easy to compute for every \(\lambda\) in a reasonable range. This is often true in competitive programming, because the constraint of the original problem is gone. The two most important questions are then
- whether there is a slope \(\lambda\) for which the minimum intercept is attained exactly at the point \((y,v(y))\), and
- if there is, how to find such a slope \(\lambda\).
The first question is the easier one. As the slope \(\lambda\) varies, the set cut out by all these lines (the intersection of their upper half-planes) is necessarily convex. So one of these lines passes through a given point if and only if the point lies on the lower hull of this convex set. This is equivalent to saying that \(v(y)\) is a convex function.
The second question is more delicate. The abscissa of the point we want is known to be \(y\), so a natural idea is to compute, along with \(h(\lambda)\), the value of the constraint function \(g(x)\) at the current optimal solution \(x_\lambda\). In the example above, when solving the penalized problem we can record how many items are chosen when the penalized objective function attains its optimum. Then compare \(g(x_\lambda)\) with the desired \(y\) and adjust \(\lambda\) for the next computation accordingly. This is the most traditional form of the Aliens trick.
To summarize, the traditional Aliens trick proceeds as follows:
- start with a reasonable interval for \(\lambda\);
- pick a \(\lambda\) in the current interval;
- solve the penalized problem \(h(\lambda)=\min_{x\in X}f(x)-\lambda g(x)\) and record \(g(x_\lambda)\), the value of \(g(x)\) at its optimal solution \(x_\lambda\);
- if \(g(x_\lambda)=y\), the optimal value of the original problem is \(v(y)=h(\lambda)+\lambda y\), and the algorithm stops;
- otherwise, adjust the interval for \(\lambda\) according to how \(g(x_\lambda)\) compares with \(y\), and go back to step 2.
This basic procedure is enough for some problems, but it is incomplete. The rest of this article improves on it.
Handling collinear points
The first problem the basic procedure runs into is that it does not handle collinear points correctly.
If three or more red points on the lower hull of \(\mathcal D\) are collinear, the basic procedure may misjudge how \(g(x_\lambda)\) compares with \(y\). For example, let three collinear red points have abscissas \(y_1,y_2,y_3\), and let the line through them have slope \(\lambda^*\). To compute \(v(y_2)\) correctly, the last problem solved before the algorithm stops must be \(h(\lambda^*)\), because \(\lambda^*\) is the only slope whose minimum-intercept line passes through the point \((y_2,v(y_2))\). But while solving \(h(\lambda^*)\), the recorded \(g(x_{\lambda^*})\) may be any of \(y_1,y_2,y_3\). If it is not \(y_2\), the algorithm wrongly continues, adjusts the interval for \(\lambda\) in the direction that leads away from \(y_2\), and ends with a wrong result.
One way to handle collinear points is to always make the recorded \(g(x_\lambda)\) of the optimal solution \(x_\lambda\) as large as possible (or as small as possible), and to change the termination condition of the binary search: instead of a \(\lambda\) with exactly \(g(x_\lambda)=y\), look for the smallest (or largest) \(\lambda\) with \(g(x_\lambda)\ge y\) (or \(g(x_\lambda)\le y\)). In the example of the previous paragraph, solving \(h(\lambda^*)\) then reports \(y_3\) as \(g(x_{\lambda^*})\), which guarantees that the last problem solved before the algorithm stops is \(h(\lambda^*)\). When implementing this, note that the final output is \(h(\lambda)+\lambda y\), not \(h(\lambda)+\lambda g(x_{\lambda})\), because the recorded \(g(x_\lambda)\) need not equal the actual constraint \(y\).
The other way is a real-valued binary search. If all numbers in the problem are integers, the slopes in the Aliens trick are clearly integers too. Real numbers are brought into the binary search so that, when the correct option \(\lambda^*\) is wrongly excluded, the fractional part lets the search work its way back and converge to the correct answer \(\lambda^*\). In the example above, if solving \(h(\lambda^*)\) records \(y_1\) as \(g(x_{\lambda^*})\), which is less than the desired \(y_2\), the algorithm moves on to the interval \((\lambda^*,\lambda_r]\), where \(\lambda_r\) is the right endpoint of the interval for \(\lambda\). With integers this interval is really \([\lambda^*+1,\lambda_r]\), which rules out ever getting close to the correct answer \(\lambda^*\) later in the algorithm. In a real-valued binary search the interval is still \((\lambda^*,\lambda_r]\), and for every \(\lambda\) in it the \(g(x_\lambda)\) recorded while solving \(h(\lambda)\) is at least \(y_3\), hence strictly greater than \(y_2\). So as the algorithm continues it keeps discarding the right half of the interval, and the final range of \(\lambda\) is guaranteed to lie near \(\lambda^*\). Since the slope we want is known to be an integer, the real-valued binary search need not run to high precision: it is enough that the final interval contains only one integer, and that integer is the \(\lambda^*\) we are looking for.
With collinear points handled correctly, the Aliens trick solves the great majority of the problems of this kind that appear in competitive programming. It still has shortcomings: it cannot handle the case where \(g(x_\lambda)\) is hard to record, nor the case of several coplanar points in a higher-dimensional Aliens trick. We now look more closely at the properties of the optimization problem \(v(y)\) and describe a more general method.
Dual method
This section describes an implementation of the Aliens trick with only two requirements. The first is that, for every \(\lambda\in\mathbf R^d\), the value
can be computed efficiently. The second is that the optimal value \(v(y)\) of the original problem is a convex function of \(y\in\mathbf R^d\)1. In one sentence: this section proves that the value function \(v(y)\) of the original problem equals the optimal value of its dual problem,
and that the objective function of the dual problem is concave in \(\lambda\in\mathbf R^d\), hence a unimodal function. The dual problem can therefore be solved efficiently by ternary search or golden-section search, still in \(O(T(n)\log^d L)\) time. This removes every difficulty that recording the value of \(g(x_\lambda)\) can cause in the traditional Aliens trick, and it lets the idea carry over to higher dimensions.
This section also shows that the range of \(g(x_\lambda)\) can be obtained from \(h(\lambda)\), without recording anything extra while solving \(h(\lambda)\). For example, when \(d=1\) and the problem involves only integers, one can prove that the range of \(g(x_\lambda)\) is exactly
For problems that have to use the binary search procedure described earlier, this is yet another way to deal with collinear points.
The rest of this section proves these results with convex analysis. For how the methods are applied, see the Example problems section.
Lagrangian duality
We attack the problem with the method of Lagrange multipliers. Introduce a Lagrange multiplier \(\lambda\in\mathbf R^d\); the Lagrangian is then
Whenever some component of \(g(x)-y\) is nonzero, the corresponding component of \(\lambda\) can be sent to (positive or negative) infinity, so
This shows that the original problem can be written as
Swapping the two extremum operations gives its dual problem:
As we show next, if \(v(y)\) is a convex function of \(y\), then strong duality holds, that is, \(v^\star(y)=v(y)\).
Convex conjugates
To show that strong duality holds, we need the notion of a convex conjugate.
Convex conjugate
The convex conjugate, or Legendre–Fenchel transformation, of a function \(f:\mathbf R^d\rightarrow\mathbf R\cup\{\pm\infty\}\) is the function
As a function of the variable \(x^*\), \(f^*(x^*)\) is the supremum of a family of linear functions, so it is necessarily a convex function on \(\mathbf R^d\).
The slope vector and intercept of a hyperplane
Every hyperplane of the vector space \(\mathbf R^{d+1}\) considered in this article has an equation of the form
In other words, this article never deals with hyperplanes parallel to the \(y\)-axis. For convenience, and without being rigorous, we call \(k\) the "slope vector" of the hyperplane and \(b\) its "intercept". Written in a more standard form, the equation of the hyperplane is
One of its normal vectors is \((k,-1)\). So the slope vector is really the first \(d\) components of the normal vector of the hyperplane, once that vector is normalized to have last component \(-1\).
Geometrically, the convex conjugate of a function \(f(x)\) says the following: among all hyperplanes with slope vector \(x^*\) that meet the epigraph
of \(f(x)\), the smallest intercept \(f(x)-x^*\cdot x\) is \(-f^*(x^*)\). In other words, \(f(x)\) always lies above the hyperplane \(y = x^*\cdot x-f^*(x^*)\) and touches it at the point \((x_0,f(x_0))\); there may of course be other points of tangency. Such a hyperplane is called a supporting hyperplane of \(f(x)\) at \(x_0\). The intercept of a supporting hyperplane of \(f(x)\) is determined uniquely by its slope vector, and the convex conjugate is exactly this map from slope vector to intercept.
Minimizing \(f(x)-\lambda\cdot g(x)\) over the set \(X\) is equivalent to minimizing \(v(y)-\lambda\cdot y\) over the set \(\{(y,v(y))\}\):
Therefore
This shows that \(h(\lambda)\) is a concave function of \(\lambda\in\mathbf R^d\). Furthermore,
That is, the value function \(v^{\star}(y)\) of the dual problem is the convex conjugate of the convex conjugate of the value function \(v(y)\) of the original problem, also called its biconjugate.
So the question becomes: which functions \(v(y)\) are equal to their own biconjugate? The following theorem answers it:
Theorem (Fenchel–Moreau)
A function \(f:\mathbf R^d\rightarrow\mathbf R\cup\{\pm\infty\}\) equals its biconjugate, that is, \(f^{**}=f\), if and only if one of the following three conditions holds:
- \(f(x)\) is a proper convex function and lower semicontinuous,
- \(f(x)\equiv+\infty\), or
- \(f(x)\equiv-\infty\).
Proof
A function is proper if and only if it never takes the value \(-\infty\) and is not identically \(+\infty\).
For improper functions, one checks that \(f(x)\equiv+\infty\) and \(f(x)\equiv-\infty\) are conjugates of each other. Apart from these, as soon as \(f(x)\) takes the value \(-\infty\) at any point, we have \(f^*(x^*)\equiv+\infty\). So these are the only two improper functions with \(f^{**}=f\). From here on we consider proper functions only. For a proper function, being lower semicontinuous and convex is equivalent to having a closed convex epigraph.
Necessity is easy. Since \(f=f^{**}\) is the convex conjugate of \(f^*\), it is a supremum of a family of linear functions, so its epigraph is an intersection of closed convex sets and hence a closed convex set. So a proper function with \(f^{**}=f\) must be lower semicontinuous and convex.
Conversely, these conditions are also sufficient. As in the proofs of other strong duality theorems, the argument has two steps.
Step one shows that weak duality holds, that is, \(f(x)\ge f^{**}(x)\). By the definition of the convex conjugate, for all \(x,x^*\in\mathbf R^d\),
Hence, for all \(x,x^*\in\mathbf R^d\), we also have
Taking the supremum over \(x^*\) on the right-hand side gives \(f(x)\ge f^{**}(x)\).
Step two uses the hyperplane separation theorem to show that \(f(x)\le f^{**}(x)\). Suppose not: there is an \(x_0\in\mathbf R^d\) with \(f(x_0)>f^{**}(x_0)\). The epigraph \(\operatorname{epi}(f)\) of \(f(x)\) is a closed convex set and the singleton \(\{(x_0,f^{**}(x_0))\}\) is a compact convex set, so by the hyperplane separation theorem there exist \((\lambda,t)\in\mathbf R^d\times\mathbf R\) and \(\alpha\in\mathbf R\) such that, for all \(x\in\operatorname{dom} f:=\{x\in\mathbf R^d:f(x)<+\infty\}\) and all \(y\ge f(x)\),
holds. Since \(y\) can be chosen arbitrarily large, we must have \(t\ge 0\). There are two cases.
First, the case \(t>0\). Divide every part of the inequality by \(t\) and set \(\lambda'=t^{-1}\lambda\) and \(\alpha'=t^{-1}\alpha\) to get
Setting \(y=f(x)\), we get for all \(x\in\operatorname{dom} f\)
Taking the supremum over \(x\) on the right-hand side,
It follows that
This contradiction rules out the case \(t>0\).
Finally, the case \(t=0\). We show that a perturbation reduces it to the case \(t>0\). Take any \(\lambda_0\in\operatorname{dom}f^*\). By the definition of the convex conjugate, for any \(x\in\operatorname{dom}f\) and \(y\ge f(x)\),
Therefore, for any \(\varepsilon>0\),
Moreover, since \(\alpha<\lambda\cdot x_0\), for sufficiently small \(\varepsilon>0\) we also have
So if we take \(\lambda'=\lambda+\varepsilon\lambda_0\), \(t'=\varepsilon\) and \(\alpha'=\alpha+\varepsilon f^*(\lambda_0)\), then
This brings us back to the previous case, which again leads to a contradiction.
This contradiction shows that no point \(x_0\in\mathbf R^d\) satisfies \(f(x_0)>f^{**}(x_0)\). Hence \(f(x_0)\le f^{**}(x_0)\) always.
Combining the two steps gives \(f^{**}(x)=f(x)\).
Therefore strong duality holds if and only if \(v(y)\) is a convex function of \(y\in\mathbf R^d\)2.
Subgradients
The previous section showed that the value function \(h(\lambda)\) of the penalized problem is the negative of the convex conjugate of the value function \(v(y)\) of the original problem. The definition of the convex conjugate is in fact a parameterized optimization problem, so a result resembling the envelope theorem holds for it as well. But a convex function is not differentiable everywhere, so the derivative must first be generalized to convex functions. This leads to the notion of a subgradient.
Subgradient
Let \(f:\mathbf R^d\rightarrow\mathbf R\cup\{\pm\infty\}\) be a convex function and \(x_0\in\operatorname{dom}f\). If a vector \(x^*\in\mathbf R^d\) satisfies, for every \(x\in\mathbf R^d\),
then \(x^*\) is called a subgradient of \(f(x)\) at \(x_0\). The set of all subgradients of \(f(x)\) at \(x_0\) is called its subdifferential there, written \(\partial f(x_0)\).
Geometrically, the subdifferential of a convex function \(f(x)\) at \(x_0\) is the set of slope vectors of all its supporting hyperplanes there. In one dimension the subdifferential is
where \(\partial_-f(x_0)\) and \(\partial_+f(x_0)\) are the left and right derivatives of \(f(x)\) at \(x_0\). Further, for the extension \(\tilde f(x)\) of a convex function \(f:\mathbf Z\rightarrow\mathbf R\cup\{\pm\infty\}\) on the integers, the left and right derivatives at an integer point \(x=k\) are the first differences on its two sides:
Clearly a convex function \(f(x)\) is differentiable at a point \(x_0\) if and only if its subdifferential \(\partial f(x_0)\) there is a singleton.
Because the convex conjugate maps the slope vector of a supporting hyperplane to its intercept, it can be used to decide whether a slope vector \(x^*\) is a subgradient of a convex function \(f(x)\) at a given point \(x\).
Theorem (convex conjugates and subgradients)
For a proper convex function \(f:\mathbf R^d\rightarrow\mathbf R\cup\{\pm\infty\}\) and any \(x,x^*\in\mathbf R^d\),
If \(f\) is also lower semicontinuous, both conditions are equivalent to \(x\in\partial f^*(x^*)\).
Proof
By the definition of a subgradient, \(x^*\in\partial f(x)\) if and only if
This is equivalent to
This in turn is equivalent to
But by the definition of the convex conjugate we always have
So the preceding inequality is in fact equivalent to the equality
This proves the first part.
When \(f\) is a lower semicontinuous proper convex function, the Fenchel–Moreau theorem gives \(f^{**}=f\). So the two conditions are equivalent to
Applying the first part once more, they are also equivalent to \(x\in\partial f^*(x^*)\).
This result says that if \(f^{**}=f\), then the subdifferential \(\partial f^{*}(x^*)\) of the convex conjugate \(f^*\) at \(x^*\) is exactly the set of \(x\)-components of the intersection points of the epigraph \(\operatorname{epi}f\) and the supporting hyperplane with slope vector \(x^*\).
Corollary
For a lower semicontinuous proper convex function \(f:\mathbf R^d\rightarrow\mathbf R\cup\{\pm\infty\}\) and any \(x,x^*\in\mathbf R^d\),
Proof
We prove the second equality; the proof of the first is similar.
By the definition of the convex conjugate,
so
if and only if \(f^*(x^*) = x^*\cdot x - f(x)\), and this equality holds if and only if \(x\in\partial f^*(x^*)\). Hence the two sets are equal.
In the setting of this article, this result says that when we solve the problem
the values of the constraint function \(g(x)\) on the set of optimal decisions are exactly \(\partial(-h(\lambda))\). When \(d=1\) and the problem involves only integers, this set is the interval
For consecutive integers \(\lambda\) these intervals are joined end to end, so a binary search only needs to compute the endpoint on one side.
Proving convexity
The Aliens trick requires the value function to be convex. In competitive programming, you can guess that convexity holds by precomputing a table of values, by intuition, and so on. Proving it rigorously, however, is often not easy. Using the following classic problem, this section presents the methods of proving convexity that are common in competitive programming.
The tree-planting problem
There are \(n\) holes and \(m\) trees to plant. Trees may not be planted in two adjacent holes. A sequence \(\{a_i\}\) of length \(n\) gives the profit of planting a tree in each hole; a profit may be positive or negative. Find the largest possible total profit of planting the \(m\) trees.
In short: find a maximum-weight independent set of size \(m\) on a path of length \(n\).
These methods fall roughly into four classes:
- reduce the claim to the convexity, in its parameters, of the value function of a convex optimization problem (including linear programming and the like); this covers methods such as building a minimum-cost flow model;
- prove convexity by induction from the recurrence, possibly using some convexity-preserving transformations along the way;
- for problems of interval partition type, verify that the cost function of each interval satisfies the quadrangle inequality;
- finally, for special problems, show convexity directly by an exchange argument.
Each of these proof methods is usually tied to some way of solving the problem.
Reduction to parametric convex optimization
Consider a parametric convex optimization problem of the following form:
Here the objective function \(f:\mathbf R^m\times\mathbf R^d\rightarrow\mathbf R\cup\{\pm\infty\}\) is convex in \(x\in\mathbf R^m\) for every \(y\in\mathbf R^d\), and the feasible region \(\mathcal D:\mathbf R^d\rightarrow \mathcal P(\mathbf R^m)\) is a set-valued function on \(\mathbf R^d\) such that \(\mathcal D(y)\) is a convex set for every \(y\in\mathbf R^d\). These conditions guarantee that this is a convex optimization problem for every parameter \(y\in\mathbf R^d\).
Theorem
Suppose that the parametric convex optimization problem above satisfies the following conditions:
- the objective function \(f(x,y)\) is a convex function of \((x,y)\);
- the graph \(\{(x,y):x\in\mathcal D(y)\}\) of the feasible region map \(y\mapsto\mathcal D(y)\) is a convex set.
If \(v(y)>-\infty\) for every \(y\in\mathbf R^d\), then the value function \(v(y)\) is a proper convex function of \(y\).
Proof
For any \(y_1,y_2\in\mathbf R^d\) and \(\alpha\in(0,1)\) we must prove
If \(v(y_1)=+\infty\) or \(v(y_2)=+\infty\), the right-hand side is \(+\infty\) and the inequality holds. Otherwise \(v(y_1)\) and \(v(y_2)\) are both finite. For any \(\varepsilon>0\) and \(i=1,2\) there is an \(x_i\in\mathcal D(y_i)\) with \(f(x_i,y_i)< v(y_i)+\varepsilon\). Since the graph of the map \(\mathcal D\) is convex,
That is, \(\alpha x_1+(1-\alpha)x_2\) is a feasible solution of the optimization problem with parameter \(\alpha y_1+(1-\alpha)y_2\). By optimality and the convexity of the objective function,
Since \(\varepsilon\) is arbitrary, letting \(\varepsilon\rightarrow 0\) gives
So the value function \(v(y)\) is convex.
In competitive programming, the most common convex optimization problems are linear programs.
Corollary
Let \(c\in\mathbf R^n\), \(A_1\in\mathbf R^{d_1\times n}\), \(A_2\in\mathbf R^{d_2\times n}\), \(y_1\in\mathbf R^{d_1}\) and \(y_2\in\mathbf R^{d_2}\). Consider the following parametric linear program:
Then the value function \(v(y_1,y_2)\) is a convex function of \((y_1,y_2)\).
Whether the constraints are inequalities or equalities, the value function of a linear program is a convex function of the parameters of the constraints.
Many graph problems can be written as linear programs:
- network flow problems: maximum flow, minimum cut, minimum-cost flow;
- shortest path problems without negative cycles;
- maximum (weight) matching, minimum vertex cover and similar problems on bipartite graphs;
- maximum (weight) matching on general graphs;
- the minimum spanning tree problem3.
So the value function of each of these problems is a convex (or concave) function of the parameters of the problem.
Integrality constraints
When a real problem is modeled as a graph problem, there are usually implicit integrality restrictions: an edge is either chosen or not, a flow must be an integer, and so on. Such a model can therefore only be turned into an integer linear programming (ILP) problem, not a linear programming (LP) problem. An ILP problem is not a convex optimization problem, so its value function need not be a convex function of the parameters of the problem. Relaxing the integrality constraints of an ILP problem gives an LP problem, but the LP problem need not have an optimal solution that satisfies the integrality constraints. So the optimal value of the LP obtained by relaxing the integrality constraints may be strictly better than that of the corresponding ILP problem; the two need not be equivalent.
All the graph problems listed above can be written as an LP problem with no integrality constraints imposed. For some other problems, such as the maximum independent set problem on general graphs, the integrality constraints are necessary. Moreover, even when a graph problem can be written as an LP, adding extra linear constraints to it may still break the equivalence between the corresponding ILP and LP problems, and then the constrained graph problem can no longer be written as a linear program.
In the setting of minimum-cost flow, for example, the following result is well known:
Corollary
In the minimum-cost flow model, the minimum cost \(v(m)\) is a convex function of the flow \(m\).
Proof
Let \(G=(V,E)\) be a directed graph in which the edge \((i,j)\) has capacity \(c_{ij}\) and cost \(w_{ij}\) per unit of flow, with source \(s\) and sink \(t\). Let the decision variables be \(\{f_{ij}\}\), where \(f_{ij}\) is the flow on the edge \((i,j)\in E\). Minimum-cost flow can then be written as the following linear program:
Hence the minimum cost \(v(m)\) is a convex function of the parameter \(m\).
Many problems in competitive programming reduce to network flow or other graph problems, and the convexity of their value functions can be established in the same way.
This method gives the first convexity proof for the tree-planting problem:
Convexity proof 1
The maximum profit in the tree-planting problem can be obtained from the following maximum-cost maximum flow model:
- add an edge of capacity \(m\) and cost \(0\) from the source \(s\) to a node \(r\);
- add an edge of capacity \(1\) and cost \(0\) from the node \(r\) to every odd node \(i=1,3,\cdots,2\lceil n/2\rceil-1\);
- add an edge of capacity \(1\) and cost \(0\) from every even node \(i=0,2,\cdots,2\lfloor n/2\rfloor\) to the sink \(t\);
- for every \(i=1,\cdots,n\), add an edge of capacity \(1\) and cost \(a_i\) from the odd node among \(i-1\) and \(i\) to the even one.
The answer is the maximum cost found. Convert this graph model into the corresponding linear program (see the proof of the corollary above); the total flow \(m\) then appears in the inequality that expresses the capacity constraint of the edge \((s,r)\). By the corollary, the maximum cost \(v(m)\) is a concave function of the flow \(m\).
With this flow model, the problem can be solved in \(O(n\log n)\) time by simulating a minimum-cost flow or by greedy with undo.
Using the recurrence
Although the recurrence does not give an efficient way to compute the answer, it can often be used to prove that the state function \(f(i,j)\) is convex in the parameter \(j\). Concretely, treat the function \(f(i,\cdot)\) as the state at \(i\); the recurrence for \(f(i,j)\) then becomes a recurrence relation for \(f(i,\cdot)\), and one can prove by induction that every \(f(i,\cdot)\) is convex. This way of proving convexity is more common in the setting of the slope trick; that page also discusses the common convexity-preserving transformations.
The same method proves convexity for the tree-planting problem:
Convexity proof 2
Let \(f(i,j)\) be the maximum profit when \(j\) trees are planted in the first \(i\) holes. Consider the recurrence
Read it as a recurrence relation for the function \(f(i,\cdot)\). The maximum involves two different functions, so it cannot be written as a supremal convolution. Even so, induction shows that \(f(i,\cdot)\) is a concave function.
What we actually prove by induction are the following two claims:
- \(f(i,j)-f(i-2,j-1)\) is decreasing in \(j\);
- \(f(i,j)-f(i-1,j)\) is increasing in \(j\).
The base case is trivial. Assume that both hold for \(i-1\) and all smaller natural numbers; we prove them for \(i\) by direct verification.
First, by the induction hypothesis,
is decreasing in \(j\). Hence
is decreasing in \(j\), and
is increasing in \(j\). This completes the induction.
It follows that
is decreasing in \(j\). So \(f(i,j)\) is concave in \(j\), and hence the value function \(v(m)=f(n,m)\) is concave in \(m\).
A by-product of this proof is that for every \(i\) there is a \(p_i\) such that
So the sequence \(f(i,\cdot)\) can be maintained directly in a balanced tree, which takes \(O(n\log^2n)\) time. In return, this handles the general case of an arbitrary required gap between trees, and it yields all the values \(v(m)\) at once.
Quadrangle inequality
Another common class of convex problems in competitive programming is the interval partition problem. That page proves that if the cost function of a single interval satisfies the quadrangle inequality, then the minimum cost of the interval partition problem with a restricted number of intervals is a convex function of the number of intervals. It also gives several ways to check whether a function \(w(l,r)\) satisfies the quadrangle inequality. The most direct one is to compute its mixed second difference:
The function \(w(l,r)\) satisfies the quadrangle inequality if and only if \(\Delta_l \Delta_r w(l,r)\) is non-positive. Intuitively, the quadrangle inequality usually means that growing the interval on both sides, that is, moving the left endpoint to the left and the right endpoint to the right, has some kind of synergy.
The tree-planting problem can also be seen as an interval partition problem, and its convexity proved by verifying the quadrangle inequality.
Convexity proof 3
Prepend an element \(a_0\), of any value, to the sequence of profits. The tree-planting problem is then equivalent to the interval partition problem of splitting the sequence \(\{a_0,a_1,\cdots,a_n\}\) into \(m\) parts, where the profit function of a part is
In other words, the profit of a part is the largest profit among its trees other than the first, and this guarantees that the trees are spaced apart.
This is a maximization problem, so we must verify that "crossing is worth no less than nesting", that is, for all \(a<b<c<d\),
Substituting the expression for the profit function and setting
the inequality to prove becomes
The larger of the two terms \(\max\{A,B\}\) and \(\max\{B,C\}\) on the left-hand side equals \(\max\{A,B,C\}\), and the smaller is never less than \(B\), so the inequality holds.
Once the tree-planting problem has been turned into an interval partition problem, it suffices to preprocess range minimum/maximum queries, with a sparse table for example, so that the cost of a single interval is computed in \(O(1)\). The algorithms for the interval partition problem then solve the problem in \(O(n\log n\log L)\) or \(O(n(n+m))\) time. This method also handles an arbitrary required gap between trees.
Exchange arguments
In combinatorial optimization, the convexity of a value function is often proved by an exchange argument. The idea is to start from optimal solutions of the problems with parameters \(m-1\) and \(m+1\) and, by exchanging some of their elements, to construct a feasible solution with parameter \(m\) whose value is at most \((v(m-1)+v(m+1))/2\); convexity then follows from the optimality of \(v(m)\). Unlike in convex optimization, combinatorial optimization has no natural way to build an "intermediate form" of two solutions, so applying an exchange argument usually takes some ingenuity.
Increasing marginal costs do not necessarily imply convexity
The objective functions of combinatorial optimization problems often have some property of "increasing marginal costs", but this does not necessarily lead to convexity. A typical example is [IOI 2005] Rivers: the version of this problem on a path satisfies the quadrangle inequality and is therefore convex, but for the version on a tree there are instances where convexity fails.
A common property used to capture "increasing marginal costs" is the supermodularity of a function. Let \(X\) be a finite set and \(f:\mathcal PX\rightarrow\mathbf R\) a function on the family \(\mathcal PX\) of its subsets. If \(f\) satisfies one of the following two equivalent properties:
- (crossing costs no more than nesting) \(f(A)+f(B) \le f(A\cup B) + f(A\cap B)\) holds for all subsets \(A,B\subseteq X\);
- (increasing marginal costs) \(f(A\cup\{x\})-f(A)\le f(B\cup\{x\})-f(B)\) holds for all subsets \(A\subseteq B\subseteq X\) and all \(x\in X\setminus B\);
then \(f\) is called supermodular. However, in an optimization problem whose objective function is supermodular, the value function
is not necessarily a convex function of \(m\). The reason is that, in general, optimal solutions whose subsets have sizes \(m-1\) and \(m+1\) cannot be used to construct a feasible solution whose subset has size \(m\) and whose value satisfies the bound stated above.
An exchange argument gives yet another proof of convexity for the tree-planting problem.
Convexity proof 4
We use an exchange argument. Let the optimal plans for planting \(m-1\) trees and \(m+1\) trees be given by \(\{x_i^{(m-1)}\}\in\{0,1\}^n\) and \(\{x_i^{(m+1)}\}\in\{0,1\}^n\), where the value \(1\) means that the hole holds a tree and the value \(0\) means that it does not. Define a sequence \(\{z_i\}\in\{0,\pm 1\}^n\) by
This sequence marks where the two plans differ. A position with value \(0\) is a hole in which either both plans plant a tree or neither does; positions with values \(-1\) and \(+1\) are holes in which only the plan \(x^{(m-1)}\), respectively only the plan \(x^{(m+1)}\), plants a tree. Since no plan may plant trees in adjacent holes, we observe:
- within a nonzero subarray, the values \(z_i\) must alternate between \(\pm 1\);
- the \(0\) on either side of a maximal nonzero subarray must be a hole in which neither plan plants a tree.
So if in some maximal nonzero subarray the \(z_i\) sum to exactly \(+1\), that is, if the plan \(x^{(m+1)}\) plants one more tree than the plan \(x^{(m-1)}\) in that stretch of holes, we can swap the tree positions of the two plans inside it. This yields two feasible plans that plant \(m\) trees each. The positions and the number of trees in the two plans taken together have not changed, only been redistributed, so the total profit is unchanged: it is still \(v(m-1)+v(m+1)\). But these two plans with \(m\) trees need not be optimal, so neither has profit greater than \(v(m)\). This proves
that is, \(v(m)\) is a concave function of \(m\).
One question remains: does a maximal nonzero subarray with sum exactly \(+1\) exist? Being a sum of alternating \(\pm 1\)'s, the sum of a nonzero subarray can only be \(0\) or \(\pm 1\). And the sums of all the maximal nonzero subarrays add up to \(2\), so there must be at least two of them with sum exactly \(+1\). This completes the proof.
Example problems
This section works through several example problems that apply the Aliens trick in different settings.
Template problems
Luogu P1484 Planting Trees
There are \(n\) holes, and at most \(m\) trees are to be planted. Trees may not be planted in two adjacent holes. A sequence \(\{a_i\}\) of length \(n\) gives the profit of planting a tree in each hole; a profit may be positive or negative. Find the largest possible total profit.
Solution
This problem differs slightly from the tree-planting problem discussed above: at most \(m\) trees are planted, not exactly \(m\). Let \(v(m)\) again denote the value function of the tree-planting problem discussed above; the answer to this problem is \(\tilde v(m)=\max_{k\le m}v(k)\). Since \(v(m)\) is concave, and so a unimodal function, the answer keeps only the part of \(v(m)\) that climbs to the peak, after which the function stays at the peak; this amounts to keeping only the part where the tangent slope is nonnegative. So the only difference from the problem discussed above is that the initial slope range of the binary search is \([0,\max_ia_i]\) instead of \([\min_ia_i,\max_ia_i]\).
Removing the count constraint with the Aliens trick turns the problem into computing a maximum-weight independent set on a path, except that the original profits \(\{a_i\}\) are replaced by \(\{a_i+k\}\). This is a classic dynamic programming problem. Let \(f(i,j)\) be the maximum profit of the subproblem on the first \(i\) holes when the \(i\)-th hole is planted (\(j=1\)) or left empty (\(j=0\)). The recurrence is
The initial conditions are \(f(0,0)=0\) and \(f(0,1)=-\infty\), and the final answer is \(\max\{f(n,0),f(n,1)\}\). One evaluation takes \(O(n)\) time and the whole algorithm takes \(O(n\log L)\), where \(L=\max_i|a_i|\).
Reference implementations:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 | |
Luogu P2619 [Chinese national training team] Tree I
Given a weighted connected undirected graph in which every edge is black or white, find the minimum weight of a spanning tree with exactly \(m\) white edges.
Solution
First, an exchange argument proves that \(v(m)\) is a convex function. We may assume that all edge weights are distinct: a case in which two edges have equal weights can be perturbed into one with distinct weights, and letting the size of the perturbation tend to zero then shows that convexity still holds in the limit, which is the case with two edges of equal weight. The key to the proof is the following lemma:4
Lemma
Let \(S\) and \(T\) be two spanning trees of a connected undirected graph \(G=(V,E)\). For every \(e\in S\setminus T\) there is at least one edge \(f\in T\setminus S\) such that \(S-e+f\) and \(T-f+e\) are both spanning trees of the graph \(G\).
Proof
Let \(e=(u,v)\) and let \(P\) be the unique path in the tree \(T\) that joins \(u\) and \(v\). Since \(P+e\) is the only cycle in the graph \(T+e\), deleting any edge \(f\) of \(P\) makes \(T-f+e\) a spanning tree. Meanwhile, the graph \(S-e\) is a forest with two connected components; call their vertex sets \(V_1\) and \(V_2\). So it suffices to choose an edge \(f\in P\) that joins \(V_1\) and \(V_2\) to make \(S-e+f\) a spanning tree. Such an edge \(f\) always exists, because \(u\) and \(v\) belong to \(V_1\) and \(V_2\) respectively and \(P\) joins \(u\) and \(v\). Moreover \(f\notin S\), because \(V_1\) and \(V_2\) are not connected in the graph \(S-e\). This completes the proof.
Let \(T_{m-1}\) and \(T_{m+1}\) be minimum spanning trees with \(m-1\) and \(m+1\) white edges respectively. Let \(e\) be a white edge of \(T_{m+1}\setminus T_{m-1}\). Applying the lemma to it gives an edge \(f\in T_{m-1}\setminus T_{m+1}\) such that \(T'=T_{m+1}-e+f\) and \(T''=T_{m-1}+e-f\) are both spanning trees. Only one pair of edges has been exchanged, so the edge weights of the trees \(T'\) and \(T''\) still sum to \(v(m-1)+v(m+1)\). There are two cases:
- If \(f\) is a black edge, then \(T'\) and \(T''\) both have \(m\) white edges, so neither has total edge weight less than \(v(m)\). This proves \(2v(m)\le v(m-1)+v(m+1)\), so \(v(m)\) is convex in \(m\).
- If \(f\) is a white edge, then \(T'\) and \(T''\) have \(m+1\) and \(m-1\) white edges respectively, so their total edge weights are at least \(v(m+1)\) and \(v(m-1)\) respectively. But as shown above, the two together weigh exactly \(v(m-1)+v(m+1)\). Hence the total edge weight of \(T'\) equals \(v(m+1)\). Comparing \(T'\) with \(T_{m+1}\) shows that \(e\) and \(f\) must have equal weights. This contradicts the assumption, so this case cannot occur.
This proves that \(v(m)\) is a convex function of \(m\).
With the convexity of \(v(m)\) established, the Aliens trick solves the problem. Remove the count constraint, subtract \(k\) from the weight of every white edge, and solve the minimum spanning tree problem, for instance with Kruskal's algorithm. With a disjoint set union maintaining connectivity, the algorithm runs in \(O(E\log E+E\alpha(V))\), where \(E\) and \(V\) are the numbers of edges and vertices and \(\alpha(\cdot)\) is the inverse Ackermann function. The dominant term \(O(E\log E)\) is the cost of sorting the edges, and in this problem it can be optimized further. The Aliens trick computes a minimum spanning tree many times, but each time only the weights of the white edges change, all by the same amount. So sort the white edges and the black edges separately during preprocessing; each time a minimum spanning tree is computed, it is then enough to merge the white edges, with their adjusted weights, and the black edges. The total complexity drops to \(O(E\log E+E\alpha(V)\log L)\), where \(L\) is the length of the range of edge weights.
Reference implementations:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 | |
Interval partition problems
Luogu P6246 [IOI 2000] Post Office, Harder Version of the Harder Version
An increasing sequence \(\{a_i\}\) of \(n\) positive integers gives the positions of \(n\) villages along a highway, and \(m\) post offices are to be built. The positions of the post offices must be chosen to minimize the sum of the distances from every village to its nearest post office. Find this minimum.
Solution
This is a typical interval partition problem. See that page for the implementation details of the binary-search queue.
Each post office serves the villages nearest to it, and these villages must be consecutive along the highway. So building \(m\) post offices amounts to partitioning the villages into \(m\) consecutive parts and building, for each part, a post office of lowest cost. It is well known that the post office should be built at the median of the village positions. The cost function of the interval \([l,r]\) is therefore
It satisfies the quadrangle inequality, because its mixed second difference is non-positive:
So the problem can be solved in \(O(n\log n\log L)\) time by combining the binary-search queue with the Aliens trick.
Reference implementations:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 | |
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 107 108 109 110 111 112 113 114 115 116 117 118 | |
Two-dimensional constraints
Codeforces 739 E. Gosha is hunting
There are \(n\) Pokémon, and the sequences \(\{p_i\}\) and \(\{q_i\}\) give the probabilities of catching the \(i\)-th Pokémon with a Poké Ball and with an Ultra Ball. At each Pokémon you may throw a Poké Ball, or an Ultra Ball, or one ball of each kind, or nothing. You have \(m_1\) Poké Balls and \(m_2\) Ultra Balls; they must be allocated well and are all thrown at the same time. Find the maximum expected number of Pokémon caught. Whether one attempt succeeds is independent of the outcomes of the other attempts.
More generally, the problem can be abstracted as follows:
Given three sequences \(\{A_i\},\{B_i\},\{C_i\}\) of positive reals, each of length \(n\), such that \(C_i\le A_i+B_i\) for all \(i=1,\cdots,n\), find optimal index sets \(X\) and \(Y\) with \(|X|=m_1\) and \(|Y|=m_2\) that maximize
Solution
The original problem is the special case of this more general problem with
So it suffices to solve the more general problem.
Let \(v(m_1,m_2)\) be the value function of this problem; we must prove that it is a concave function of \((m_1,m_2)\). Consider the following flow model:
- add an edge from the source \(s\) to each of the nodes \(x\) and \(y\), with capacities \(m_1\) and \(m_2\) respectively and cost \(0\) for both;
- for every \(i=1,\cdots,n\), add an edge from each of the nodes \(x\) and \(y\) to the node \(i\), both of capacity \(1\), with costs \(A_i\) and \(B_i\) respectively;
- for every \(i=1,\cdots,n\), add two edges from the node \(i\) to the sink \(t\), both of capacity \(1\), with costs \(0\) and \(C_i-A_i-B_i\).
The answer to the problem is the maximum-cost maximum flow of this model. The condition \(C_i-A_i-B_i\le 0\) guarantees that when the flow through the node \(i\) is \(1\), it leaves through the edge of cost \(0\) first. Write the flow model as a linear program; then \(m_1\) and \(m_2\) appear in the inequalities that express the capacity constraints of the edges \((s,x)\) and \((s,y)\) respectively. Hence \(v(m_1,m_2)\) is indeed a concave function of \((m_1,m_2)\).
To apply the Aliens trick, consider the optimization problem with the count constraints removed. Let \(k_1\) and \(k_2\) be the bonuses gained for putting an index into the sets \(X\) and \(Y\) respectively. Without the count constraints the decisions for the individual indices are independent, so
The answer to the original problem is given by
The total running time is \(O(n\log^2L)\), where \(O(\log L)\) is the number of steps of the binary search in a single dimension.
A reference implementation for the Pokémon problem:
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 | |
More general constraints
Codeforces 1661 F. Teleporters
There are \(n\) segments whose lengths are given by the sequence \(\{a_i\}\). They may be cut arbitrarily into segments of integer length, and the goal is to minimize the sum of the squares of the lengths of all segments. Find the minimum number of cuts needed to bring this sum of squares down to at most \(V\).
Solution
Let \(f(a,m)\) be the smallest sum of squares obtainable by cutting a segment of length \(a\) exactly \(m\) times. By the AM-GM inequality, when the sum of two numbers is fixed, the smaller their difference, the smaller the sum of their squares. So the more even the lengths of the segments after cutting, the smaller the total sum of squared lengths. Because of the integrality constraint, however, the most even outcome consists of \(a\bmod (m+1)\) segments of length \(\lceil a/(m+1)\rceil\) and \(m+1-(a\bmod (m+1))\) segments of length \(\lfloor a/(m+1)\rfloor\). This gives the expression
The second equality holds because \(\lceil a/(m+1)\rceil \neq \lfloor a/(m+1)\rfloor + 1\) if and only if \(a\bmod (m+1) = 0\).
One can prove that \(f(a,m)\) is a convex function of \(m\). To do so, extend it to \(m\in\mathbf R_{+}\). When \(\lfloor a/(m+1)\rfloor = q\),
This is a line of slope \(-q(q+1)\). So \(f(a,m)\) is a piecewise linear function whose slope increases as \(m\) increases. Hence \(f(a,m)\) is a convex function, and its restriction to the integer points is of course convex as well5.
With \(f(\cdot,\cdot)\), the smallest sum of squares obtainable with \(m\) cuts in total over all segments is the value function of the following optimization problem:
This is the infimal convolution of several convex functions, so it is a convex function too. If the problem asked for \(v(m)\), the method of the earlier examples would solve it in \(O(n\log^2L)\) time. But this problem asks for the smallest \(m\) with \(v(m)\le V\). Computing \(v(m)\) with the Aliens trick and then binary searching on \(m\) will not do: that takes \(O(n\log^3L)\) time. There are two ways to handle this problem.
Method 1: still binary search on the slope \(k\), but base the search on estimates of upper and lower bounds on \(v(m)\).
In the traditional Aliens trick, a given slope \(k\) determines the range of the corresponding optimal values of \(m\). The points \((m,v(m))\) in question are collinear, so this also determines the range of \(v(m)\). We can therefore binary search on the slope \(k\) directly. Once the slope \(k\) is found, the equation of the line,
gives the smallest \(m\). The whole algorithm takes \(O(n\log^2L)\) time.
To determine the range of \(v(m)\) we need the range of \(m\). One option is to record the largest optimal solution while computing \(h(k)\), from which a lower bound on the corresponding \(v(m)\) follows. Another is to obtain an upper bound on the corresponding \(m\) from \(h(k)-h(k-1)\), and from it a lower bound on the corresponding \(v(m)\). The reference implementation uses the second option: it does not depend on the structure of the particular problem and needs no special handling.
Method 2: rewrite the optimization problem so that the value function of the dual problem is the answer to this problem.
This problem can be read directly as the following optimization problem:
The analysis of this article still applies to it, so the required \(m(V)\) can be found from its dual problem:
The whole algorithm again takes \(O(n\log^2L)\) time.
Reference code:
The code is for illustration only. To pass under the constraints of the original problem, it needs 128-bit integers and the initial interval of the binary search changed to \([0,10^{60}]\).
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 | |
The code is for illustration only. Because of floating-point precision, it does not pass under the constraints of the original problem.
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 86 87 88 89 90 91 92 93 94 95 96 97 98 99 100 101 102 103 104 105 106 | |
Practice problems
Finally, here are some problems that can be solved with the Aliens trick, for practice:
- Luogu P1484 Planting Trees
- Luogu P1792 [Chinese national training team] Planting Trees
- Luogu P2619 [Chinese national training team] Tree I
- Luogu P3620 [APIO/CTSC2007] Data Backup
- Luogu P4072 [SDOI2016] Journey
- Luogu P4383 [Eight-Province Joint Team Selection 2018] Link-Cut Tree
- Luogu P4983 Forgetting Feelings
- Luogu P5308 [COCI 2018/2019 #4] Akvizna
- Luogu P5633 Minimum Degree-Constrained Spanning Tree
- Luogu P5896 [IOI 2016] aliens
- Luogu P6246 [IOI 2000] Post Office, Harder Version of the Harder Version
- AtCoder Beginner Contest 218 H - Red and Blue Lamps
- AtCoder Beginner Contest 305 Ex - Shojin
- AtCoder Regular Contest 164 E - Segment-Tree Optimization
- Codeforces 125 E. MST Company
- Codeforces 321 E. Ciel and Gondolas
- Codeforces 739 E. Gosha is hunting
- Codeforces 802 O. April Fools' Problem (hard)
- Codeforces 958 E2. Guard Duty (medium)
- Codeforces 1279 F. New Year and Handle Change
- Codeforces 1661 F. Teleporters
- Codeforces 1799 F. Halve or Subtract
- 2019 Summer Petrozavodsk Camp H. Honorable Mention
References and notes
- Qinshi Wang, On a Class of Binary-Search Methods (in Chinese)
- Theoretical grounds of lambda optimization by adamant - Codeforces blog
- A Rigorous Approach to WQS Binary Search by YeahPotato - Luogu Blog (in Chinese)
- [Study Notes] WQS Binary Search Explained in Detail, with Common Misconceptions Cleared Up by ikrvxt - CSDN Blog (in Chinese)
- Convex conjugate - Wikipedia
- Fenchel–Moreau theorem - Wikipedia
- Subderivative - Wikipedia
- Boyd, Stephen P., and Lieven Vandenberghe. Convex optimization. Cambridge university press, 2004.
- Papadimitriou, Christos H., and Kenneth Steiglitz. Combinatorial optimization: algorithms and complexity. Courier Corporation, 1998.
- Conforti, Michele, Gérard Cornuéjols, and Giacomo Zambelli. Integer programming. Springer International Publishing, 2014.
- Schrijver, Alexander. Combinatorial optimization: polyhedra and efficiency. Vol. 24, no. 2. Berlin: Springer, 2003.
-
In an actual problem, \(y\) may only be able to take finitely many lattice points of \(\mathbf R^d\). What is really required here is that the solution \(v(y)\) of the original problem can be extended to a convex function \(\tilde v:\mathbf R^d\rightarrow \mathbf R\cup\{\pm\infty\}\) on \(\mathbf R^d\), that is, that \(v(y)\) is convex-extensible. For convenience, the main text still writes \(v(y)\) for the extended function. Geometrically, this says that all points of the set \(\{(y,v(y))\}\) lie on the lower hull of their convex hull. In one dimension this condition is easy to characterize algebraically; in higher dimensions it is somewhat more complicated, and these lecture notes give some simple sufficient conditions. ↩
-
The condition in the theorem looks somewhat stronger than convexity, but in the situations that arise in competitive programming, in particular when \(X\) is a finite set, insisting on convexity alone is enough. The function \(\tilde v\) obtained by extending a proper convex function \(v\) on a discrete set is necessarily a lower semicontinuous convex function: the convex hull of finitely many points is a closed convex set, and a convex function is lower semicontinuous exactly when its epigraph is a closed convex set. As for the word "proper" in "proper convex function", it is guaranteed as soon as \(v(y)\) is a convex function that takes a finite value at at least one point. ↩
-
There are two common ways of writing the minimum spanning tree problem as a linear program: the subtour-elimination formulation and the cut-based formulation. Only the former guarantees that the resulting linear program is equivalent to the original problem. ↩
-
This lemma also holds for general matroids, where it is called the symmetric basis-exchange property; see the Wikipedia page. The convexity result of this problem therefore generalizes to arbitrary matroids. ↩
-
Of course, \(f(a,m)\) is not the same as the convex hull of the function obtained by restricting it to the integer points, because \(f(a,m)\) may have extreme points at non-integer positions. So the \(f(a,m)\) whose domain is the reals cannot be used directly in the optimization problem of this problem. ↩
This page is an unofficial English translation of the original OI Wiki page (revision 9bb3a8e6), machine-translated by Claude Fable 5.2 on 2026-11-16. It has been modified from the original by translation and may contain errors. It is not endorsed by OI Wiki.
Found a translation problem? Report it on GitHub.
Authors of the original page: c-forrest, HeRaNO, jyeric, Tiphereth-A (full contribution history)
All content on this page is provided under the terms of CC BY-SA 4.0 and SATA; additional terms may apply.